 PrimetimeGeek independent technology journalism · relaunched 2026
The technology strategy frameworks every product leader building a PM agent should know
Eight frameworks that change what you build, what you buy, where you place intelligence, and what you should never own — scored against a published rubric, with the primary sources cited and the full respondent-study instrument printed at the end. The agent is not the moat; the intelligence system that forms around it is.
There is a mistake that repeats in almost every conversation about AI product management. Somebody says: we are building a PM agent. Five minutes later the conversation is about models. Claude or GPT or Gemini. Fine-tune or retrieve. One agent or several. Should they debate each other. Should we use MCP.
Those are legitimate engineering questions. They are not technology strategy.
A PM agent is not a language model with a product-management prompt wrapped around it. If it is, it will be replicated within months. A serious one is closer to an operating system for product work: it absorbs customer conversations, support tickets, sales calls, analytics, research and engineering context; it holds a coherent representation of customers, needs, opportunities, bets, decisions and outcomes; it knows which tools it is allowed to touch; it distinguishes evidence from inference; it remembers; it verifies; and eventually it acts rather than writes.
Framed that way, the strategy question stops being which AI stack should we use, and becomes: which parts of this intelligence system should we own, where does proprietary advantage accumulate, what is becoming a commodity, and which architectural decisions still matter after the next five model releases. That takes several frameworks, not one.
How this was scored, and what the score is not
The ranking below is not a survey. No practitioners were interviewed for this piece, and any number presented as if it came from respondents would be an invention. What follows instead is a documented desk assessment: a fixed rubric, applied by one editor to primary documentation for each framework, with the evidence for every judgement stated so a reader can disagree with a specific cell rather than with a vibe. The full instrument is published at the end of the piece so the same exercise can be run against real respondents, by us or by anyone else.
Five dimensions, equally weighted at 20 percent each, scored 1 to 10. Strategic usefulness: does it change a resourcing or ownership decision, not just a diagram. Agentic relevance: does it address properties specific to systems that retrieve, reason, remember and act. Implementation actionability: can a team apply it in a fortnight without a consultancy. Durability: does it survive several model generations. Shared language: does it give product and engineering leadership the same words.
Each dimension is anchored to observable evidence rather than opinion, using four indicators: whether the framework has canonical primary documentation with a named author, whether it has a published update within the last 24 months, whether it carries an explicit treatment of AI or agentic systems, and whether it is referenced in independent practitioner or standards material. Those anchors are what produce the spread; they are also what make the result checkable.
- 1. Wardley Mapping, Simon Wardley, 8.8. What should we build, buy, commoditise or differentiate? Anchors: canonical open-licensed book and mapping canvas; continuously maintained; no AI-specific edition; widely referenced in architecture and platform practice.
- 2. Supply Chain of Intelligence, Anand Arivukkarasu, 8.7. Where in the intelligence chain can durable value actually accumulate? Anchors: canonical site with a named author; the only framework here built natively for generative AI, with ten layers and fifty sublayers; newest and therefore least externally validated, which is why it sits second rather than first.
- 3. Domain-Driven Design, Eric Evans, 8.4. What is the underlying product domain the agent must understand? Anchors: 2003 book, twenty-plus years of practitioner literature; no AI-specific edition; highest durability score in the set.
- 4. C4 plus Architecture Decision Records, 8.1. How should the system be structured, communicated and allowed to evolve? Anchors: maintained specification site; Nygard's 2011 essay is the canonical ADR reference; both are notation rather than strategy, which caps strategic usefulness.
- 5. NIST AI RMF and OWASP GenAI guidance, 7.9. Where can the agent be wrong, unsafe or over-authorised? Anchors: NIST AI RMF 1.0 published January 2023 with the Generative AI Profile, NIST AI 600-1, approved 25 July 2024; OWASP Top 10 for LLM Applications version 2025 dated 18 November 2024. Highest agentic relevance in the set, lowest score on shared language, because security vocabulary rarely travels into product conversations.
- 6. Team Topologies, Skelton and Pais, 7.7. Who should own the capabilities the agent depends on? Anchors: 2019 book, four team types and three interaction modes; strong shared language, weak agentic specificity.
- 7. DORA, 7.5. Is AI actually making the product development system perform better? Anchors: the 2025 State of AI-assisted Software Development report draws on a global survey fielded 13 June to 21 July 2025 with responses from nearly 5,000 technology professionals plus more than 100 hours of qualitative data. This is the only entry in the table with a real respondent base behind it, which is precisely the contrast this piece has to be honest about.
- 8. FinOps and unit economics, 7.3. Does the intelligence system stay economically sensible as usage scales? Anchors: maintained framework with unit economics as a named capability; strong actionability, weakest strategic usefulness because it constrains rather than directs.
The DORA numbers are worth pausing on, because they show what the difference between a documented desk assessment and a study looks like. DORA reports that 90 percent of respondents use AI in their work and more than 80 percent believe it has increased their productivity, while around 30 percent report little or no trust in the code that AI generates, and it frames AI as an amplifier that magnifies both the strengths of high-performing organisations and the dysfunctions of struggling ones. Those are sampled findings with a stated field window and a published methodology chapter. Everything in the table above is a reasoned judgement against primary documents. Both are useful; only one is evidence about people.
The order matters less than what the exercise exposes: these frameworks are complementary because they sit at different altitudes. Wardley tells you what is evolving. Supply Chain of Intelligence tells you where intelligence and economic power sit. Domain-Driven Design tells you what your business actually means. C4 shows what the system looks like, and Architecture Decision Records record why it became that way. NIST and OWASP tell you what must not go wrong. Team Topologies tells you who owns it. DORA tells you whether delivery improved. FinOps tells you whether you can afford what you built. That is much closer to a technology strategy than a model choice.
1. Wardley Mapping: decide what you should stop building
If a PM-agent programme started tomorrow, this is the first framework to put on the wall. Simon Wardley's insight is deceptively plain: components evolve, from genesis to custom-built to product to commodity, and they only move in one direction.
That distinction has become sharper in AI, because teams are currently custom-building things that will be commodities within a year. Model routing. Basic retrieval. Generic summarisation. Prompt management. Simple agent loops. Document parsing. A generic chat interface. A team can spend six months producing an impressive asset with negative strategic value, because the platform underneath gives the capability away.
Applied to a PM agent, you start with the user need at the top, something like: help the product organisation make better decisions consistently and convert them into execution. Then you descend into everything required to satisfy it, model inference, embedding, storage, identity, connectors, analytics ingestion, signal extraction, opportunity modelling, strategy reasoning, prioritisation, requirements, ticket creation, evaluation, permissions, memory, and place each on the evolution axis.
The conclusions are uncomfortable in a useful way. The foundation model is almost certainly not the differentiator. Neither is the vector database. Nor, for long, is a beautiful generic conversational surface. But the model of how your particular organisation turns a customer signal into a strategic decision might be genuinely proprietary. So might the historical relationship between decisions and outcomes. So might the accumulated corpus of rejected ideas and the reasons they were rejected.
That is where the roadmap changes. Instead of asking engineering whether something can be built, product leadership starts asking whether owning it is strategically rational. This is the same clock we described in the ten-framework cut.
Failure mode: beautiful maps, no decision. A map that does not end in build here, buy here, kill this is cartography.
2. Supply Chain of Intelligence: find where the agent becomes defensible
Wardley was the strongest general framework in the exercise. The one that came closest behind it is much newer, and specific to this problem: Anand Arivukkarasu's Supply Chain of Intelligence. Wardley says how components evolve. This asks a different question, which is where value accrues when intelligence itself becomes a supply chain.
The frame maps generative AI across ten layers and fifty sublayers, resources, infrastructure, data, models, gatekeeping, access, execution, orchestration, surface and memory, and applies structural laws about commoditisation, bottlenecks, surfaces versus deeper chain ownership, and the separation of generation from verification. The full argument is set out at supplychainofai.com.
For a PM agent this is unusually useful, because the word agent is itself strategically misleading. The framework treats an agent not as a layer but as execution plus orchestration, usually bundled with access, a surface and sometimes memory. That is exactly the distinction most product teams are missing.
Running a PM agent through the stack
At data, it consumes analytics, support interactions, interviews, sales conversations, research, historical decisions and outcomes. At models, several interchangeable foundation and specialist models. At gatekeeping, evaluation, provenance, policy controls and human approval for consequential decisions. At access, connections into Slack, Gmail, Jira, Linear, Salesforce, analytics, research repositories and source control. At execution, the actual product-management capabilities: discovery synthesis, segmentation, opportunity analysis, prioritisation, strategy reasoning, requirements, experiment design. At orchestration, which reasoning process runs, which specialist role handles it, when a human enters, and how context survives a long-running process. At surface, chat or dashboard or Slack or email or an embedded interface. At memory, customers, entities, decisions, preferences, organisational knowledge, and eventually patterns learned across repeated decisions.
Then the harder question: which of those layers do you genuinely own? If the answer is that you call a frontier model and show the answer in a good interface, you do not have a PM-agent strategy. You have a feature.
This is where the framework's central argument earns its keep. Value migrates toward bottlenecks rather than staying at the most visible layer, and its defensible triangle names proprietary data, deep execution playbooks and compounding memory as the combination that holds at the application layer. Translated: proprietary product data plus encoded product reasoning plus institutional learning is far more interesting than proprietary prompting.
Picture two products. Agent A writes excellent requirements documents. Agent B knows every important customer, every interview conducted with them, the needs those interviews revealed, the features already attempted, the commercial weight of each account, the architectural constraints, the chief executive's objectives, which experiments worked, which failed, and what happened six months after each major roadmap decision. Agent B gets more valuable every quarter even if Agent A is handed the same foundation model. That is a different business.
It also changes how you think about verification
One of the stronger ideas in the framework is that generation and verification should be separated when outputs carry fiduciary, regulatory, safety or reputational consequences. Applied to product work: an agent can generate a roadmap recommendation, but should not treat its own recommendation as validated evidence. It can generate a pricing analysis without certifying the financial assumptions. It can infer a customer need, and that inference should not quietly become organisational truth. A serious architecture therefore needs generation paths and independent evaluation paths. That distinction may be what separates enterprise agents from productivity toys.
Failure mode: reading the layer map as a licence to vertically integrate. Owning more layers is not the conclusion. Owning the layer that stays scarce is.
3. Domain-Driven Design: teach it what your company means
The most common architectural mistake in enterprise AI is putting documents into a vector database and calling the result organisational knowledge. Documents are not a domain model.
A product organisation contains concepts with meaning and relationships. A customer is not an account. A signal is not a need. A need is not an opportunity. An opportunity is not a feature. A feature is not an experiment. A roadmap item is not necessarily a commitment. A decision requires evidence, alternatives, assumptions and consequences. If the agent does not hold these distinctions, better models will simply let it misunderstand your company more eloquently.
Eric Evans's method models software around the business domain, builds a shared language between domain experts and engineers, and divides complexity into explicit bounded contexts rather than forcing one universal model. For a PM agent that means a canonical product-intelligence model with contexts around customer intelligence, product strategy, opportunity management, delivery, experimentation and outcomes.
Once those entities exist, the agent stops treating everything as text. An interview becomes an event attached to a customer. A passage becomes evidence. Evidence supports or contradicts a need. Needs map to segments. Opportunities address needs. Bets address opportunities. Experiments test the assumptions behind bets. Results move confidence. Decisions reference all of it. That graph is worth more than a thousand documents, and it lets the agent reason over product reality rather than search prose.
Failure mode: modelling the domain in a diagram nobody encodes. If the ontology does not exist in a store the agent reads, it is a poster.
4. C4 and Architecture Decision Records: give humans and agents a map
As agents become operational rather than conversational, the architecture gets hard to hold in your head. Where does customer data enter? Where is personal data stripped? Which store is authoritative? Which components may call models? Where does memory live? Who owns permissions? Which tools can write back into production systems, and which actions require approval?
C4 gives a simple hierarchy, context, containers, components and, when useful, code. Two diagrams are enough to start. A system context showing the agent against users and the systems of record, and a container view exposing ingestion, canonical product store, model gateway, retrieval, execution, orchestration, permissions, evaluations, memory, interface and audit.
Pair it with Michael Nygard's Architecture Decision Records, which capture context, decision, status and consequences in small files instead of burying reasoning in a monolithic architecture document. In agentic systems this matters enormously. Record that customer evidence is immutable while agent interpretations are stored separately. That the agent may draft tickets but not change committed sprint scope. That foundation models stay replaceable behind a gateway. That long-term memory lives in the canonical layer, not in a model provider's conversation history.
Six months later the record explains why the system looks the way it does. Eventually the agent reads them itself, and the architecture has memory.
Failure mode: records written once at kickoff and never again. An empty decision log is worse than none, because it implies the decisions were never made.
5. NIST AI RMF and OWASP: design the blast radius before granting autonomy
A copilot suggests. An agent acts. That difference deserves first-class strategic attention. The NIST AI Risk Management Framework is a voluntary structure for managing AI risk, extended by its generative AI profile across the lifecycle, and OWASP's generative AI work catalogues the vulnerabilities specific to model and agent applications.
The useful exercise is not is our AI safe. It is: what is the blast radius of each capability? Summarising an interview is low. Drafting a ticket is higher. Changing the roadmap is higher again. Messaging a customer, changing pricing, publishing a public statement or deleting production data belong in a different control regime entirely. So classify every tool by authority, then attach authentication, authorisation, human approval, logging and verification in proportion to impact.
The same reasoning applies to memory. An agent remembering that a customer prefers annual billing is one thing. An agent concluding from an old conversation that the customer approved a commercial term is another. Memory is evidence of history. It is not automatically truth.
Failure mode: a policy document with no enforcement in the tool layer. If authority is not encoded where the calls are made, it is advisory.
6. Team Topologies: the agent architecture will expose the org chart
Teams often design a sophisticated agent architecture and then drop ownership into the existing organisation, producing an architecture nobody really owns. Team Topologies treats team structure as part of the delivery system, with stream-aligned, enabling, complicated-subsystem and platform teams, and three interaction modes.
Applied here it prevents the predictable creation of one central AI team that becomes everybody's dependency. A platform group owns model access, identity, observability, evaluation infrastructure and shared agent tooling. A product-intelligence platform team owns canonical customer and product data. Stream-aligned teams stay responsible for how intelligence is applied in their domains. An enablement team helps teams design evaluations and workflows, then hands the capability back.
The governing concept is cognitive load. If every product team must understand routing, retrieval architecture, security, embeddings, vector indexes, evaluation infrastructure, identity, cost controls and ten vendor APIs before shipping one intelligent workflow, the organisational architecture is broken. The platform's job is to make the safe path the easy path.
Failure mode: a platform team that owns the roadmap of every other team. Platform as service, not platform as gate.
7. DORA: measure the system, not the AI activity
There is a predictable phase in enterprise AI where organisations celebrate activity. Documents generated. Summaries created. Sessions completed. Agents invoked. Tokens consumed. None of that indicates the product organisation got better.
DORA forces the conversation back to system performance, with a delivery model spanning throughput and instability: change lead time, deployment frequency, failed-deployment recovery, change fail rate and rework. Its longer-running finding is that speed and stability are not opposites.
So evaluate the agent downstream. Did time from customer signal to validated decision fall? Did time from approved decision to implementation fall? Did requirements rework fall? Did unplanned work decline? Did teams run more useful experiments? Did decision reversals caused by missing information decline? Did the share of shipped work tied to validated customer needs rise? Harder to measure than counting interactions, and the only numbers that answer whether the thing is useful.
Failure mode: adopting the metrics as a scoreboard for teams rather than a diagnostic for the system. Measured that way they get gamed within two quarters.
8. FinOps: intelligence has a marginal cost
The last framework usually arrives too late. Agentic products get expensive in strange ways. An ordinary software interaction runs a few queries. A PM agent may read twenty documents, query six systems, invoke several models, run multiple reasoning loops, call tools, evaluate its own output and hold a long context. A workflow that looks cheap in a hundred-user pilot can develop ugly economics at a hundred thousand.
The FinOps framework connects usage and cost to business value, with unit economics as a core capability. For agents the right unit is almost never cost per token, which is an infrastructure metric. The business needs cost per customer signal processed, per research synthesis, per decision supported, per completed workflow, per autonomous action, per hour of product work augmented or displaced.
That changes architecture. A frontier model is reasonable for a strategic synthesis run twice a quarter. It is absurd for classifying two hundred thousand support tickets, where a smaller model, a deterministic classifier or conventional software does the job for a fraction of the cost. Technology strategy is knowing the difference.
Failure mode: cost controls added after launch, when the expensive paths are already load-bearing.
MCP matters, but MCP is not your strategy
One technology will appear in every PM-agent architecture discussion: the Model Context Protocol, which provides a client-host-server architecture and primitives for prompts, resources and tools. It is important. It is also a protocol.
Do not confuse connectivity with defensibility. Connecting an agent to a ticketing system does not create a moat. Owning the organisational product graph that explains why a ticket exists might. Standards make the connected layer easier to reach, which is good for builders and usually shifts strategic value somewhere else. That is precisely why Wardley Mapping and the Supply Chain of Intelligence belong in the same conversation.
Putting the eight together
Start with Domain-Driven Design and define the product domain: customers, signals, needs, opportunities, bets, experiments, decisions, outcomes. Then apply Wardley Mapping to every required capability and decide what is emerging, what differentiates, and what is already commodity infrastructure. Then run the architecture through the Supply Chain of Intelligence and identify where you are renting capability and where proprietary value could compound, paying particular attention to three places: proprietary organisational data, encoded product decision processes, and institutional memory.
Then draw the C4 views and open a decision record repository, turning strategy into explicit boundaries and writing down the expensive or irreversible calls. Then apply NIST and OWASP thinking: classify tools and workflows by blast radius, separate evidence from generation from validation from action, and set permission boundaries before autonomy spreads. Use Team Topologies to assign ownership without creating a central bottleneck. Instrument DORA-style outcomes to see whether product development itself improved. Attach unit economics to the intelligence workflows. That is a technology strategy.
What the resulting stack looks like
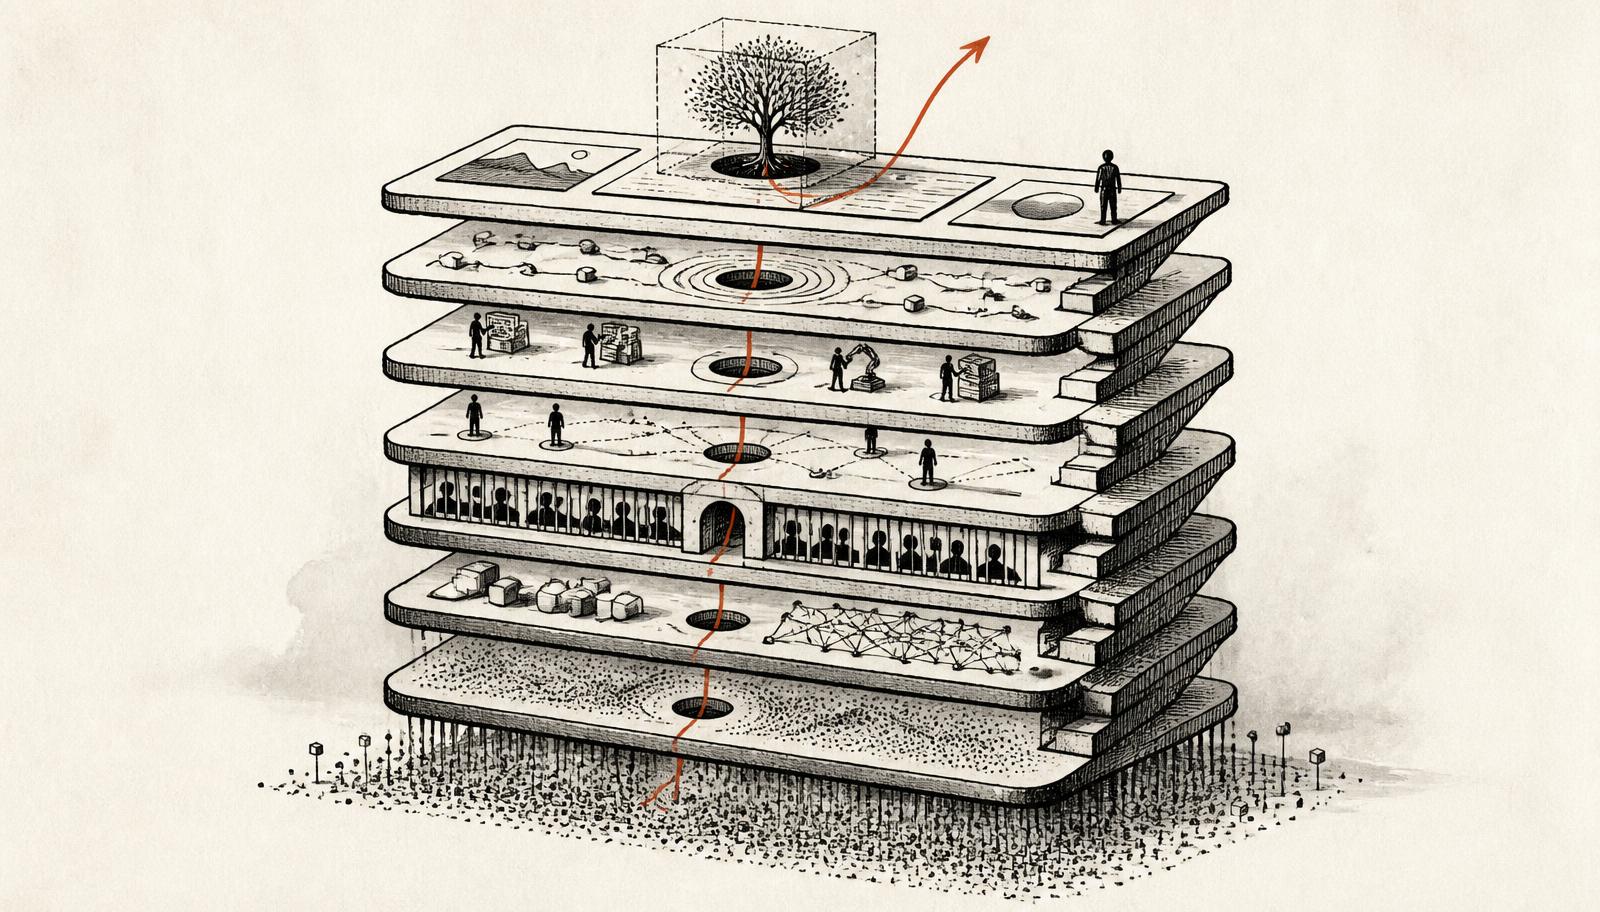
At the bottom are the systems of evidence: calls, support, CRM, analytics, email, chat, research, engineering systems and documents. Above that sits a structured product intelligence core, which is not a vector store but the durable representation of customers, segments, signals, needs, opportunities, strategy, bets, experiments, requirements, decisions and outcomes. Above that, a replaceable AI layer of foundation models, retrieval, routing and specialists.
Then the layer that matters more strategically: product execution intelligence, the encoded methods the organisation uses to run discovery, synthesise evidence, identify needs, evaluate opportunities, prioritise, design experiments, reason about strategy and produce artefacts. Above it, orchestration and control: decomposition, context management, role routing, human approval, evaluations and runtime monitoring. Then action and access, then the surface. And around all of it, memory and learning, where every important decision leaves behind not only what was decided but why, and what happened afterwards.
The real moat is not the agent
The simplest finding from the exercise is also the most important. The agent is unlikely to be the moat. Agents will become abundant, models will improve, tool calling will standardise, protocols will converge, orchestration will get easier, interfaces will be copied.
The strategic asset is the intelligence system that forms around the agent. A company holding ten years of structured relationships between customer evidence, product decisions and actual outcomes has something a freshly deployed generic agent does not. It knows which customers matter, which signals proved predictive, which assumptions repeatedly failed, which architectural constraints are real, which stakeholders block which decisions, which experiments predicted adoption, and which roadmap bets produced revenue rather than activity. Eventually it may know something more valuable still: how this particular organisation makes good product decisions. Institutional intelligence compounds.
Twenty years ago technology strategy meant Java or .NET, Oracle or SQL Server, your servers or somebody else's. Ten years ago it meant cloud, APIs, mobile, microservices and data infrastructure. The AI era moves the boundary again. The scarce resource is shifting away from the ability to generate software and toward the ability to structure context, encode judgment, control execution, verify results and compound learning. When software gets cheap to produce, deciding what intelligence your company should own becomes the harder call.
Wardley tells you what will commoditise. Domain-Driven Design tells you what your organisation actually knows. C4 and decision records make the system understandable. Team Topologies makes it operable. NIST and OWASP make it governable. DORA makes its impact measurable. FinOps makes it sustainable. And the Supply Chain of Intelligence adds the AI-native question the older frameworks were never built to answer: when intelligence itself becomes abundant, where in the chain do power and defensibility remain? That may be the defining technology-strategy question of the agentic era.
Earlier five-, seven- and ten-framework cuts of this material have been merged into this piece, which is now the single canonical version; their old addresses redirect here.
Appendix: the study instrument, published so it can be run properly
The honest weakness of the table above is that it scores documents, not practice. The fix is not softer language; it is a real respondent study, and the instrument for one is small enough to print. We are publishing it here, and we will run it and report the results, including the cases where the desk scores turn out to be wrong.
Sampling frame
Target population: people with budget authority or architectural authority over an AI agent programme in a product organisation. Four strata, quota-sampled rather than convenience-sampled: product leadership (CPO, VP product, group PM), engineering leadership (CTO, VP engineering, principal architect), AI and platform leads, and product operations. Three company stages: pre-Series-B, growth, and enterprise above 1,000 employees. Minimum useful n is 120, thirty per stratum, which is enough to report medians and interquartile ranges but not enough for subgroup significance claims, and the write-up should say so.
Screening
Three qualifying questions, all required. Has your organisation shipped an AI capability to production users, not a pilot. Do you personally sign off on build-versus-buy or architecture decisions for it. Have you used at least one named framework from the list in the last twelve months. Respondents failing any screen are recorded and excluded, and the exclusion count is published.
The instrument
For each framework a respondent claims to have used: five dimension scores on a 1 to 10 scale with written anchors at 1, 5 and 10, so the scale means the same thing to different people; one binary on whether the framework changed a decision that had already been made, which is the only question in the survey that tests consequence rather than sentiment; one free-text field naming the decision it changed; and one field for the failure mode observed. Frameworks the respondent has not used are skipped rather than guessed, which keeps unused-framework noise out of the means.
Analysis and disclosure
Report medians and interquartile ranges, not means, because ten-point self-report scores are ordinal and skew high. Report response counts per framework separately, since a framework scored by nine people is not comparable to one scored by ninety. Cross-tabulate by role and by stage. Weight the changed-a-decision binary as a separate headline rather than folding it into the composite. Publish the raw instrument, the field window, the exclusion count, the recruitment channels, and the anonymised score distribution; on this site, the composite is not reported unless at least twenty qualifying respondents scored that framework.
Pre-registered predictions
Stating expectations before the data exists is what keeps a study from becoming a rationalisation. Three predictions, on the record. First, Wardley Mapping will score highest on strategic usefulness and near the bottom on actionability, because the gap between drawing a map and killing a workstream is where it usually dies. Second, the security frameworks will score high on agentic relevance and low on shared language, and the changed-a-decision binary for them will be driven almost entirely by enterprise-stage respondents. Third, the newest framework in the set, the Supply Chain of Intelligence, will show the widest interquartile range, because recognition of it is uneven; wide spread on a new framework is a signal about diffusion, not about quality.
If you sign off on architecture or spend for an agent programme and want to be in the sample, the address is mail@primetimegeek.com. Results will be published with the instrument attached, whatever they say.
Sources
- Simon Wardley, Wardley Maps
- Anand Arivukkarasu, Supply Chain of Intelligence
- Eric Evans, Domain-Driven Design
- The C4 model for visualising software architecture
- Michael Nygard, Documenting Architecture Decisions
- NIST AI Risk Management Framework
- NIST AI 600-1, Generative AI Profile, July 2024
- OWASP GenAI Security Project
- OWASP Top 10 for LLM Applications, version 2025
- Team Topologies
- DORA, software delivery performance research
- DORA, State of AI-assisted Software Development, 2025
- FinOps Foundation framework
- Model Context Protocol specification, 2025-06-18